Computing
Redefining computing for the future
A runtime reconfigurable processor architecture for AI, telecom, HPC, edge intelligence, and next generation data centres. REDEFINE™ reshapes its compute fabric to the demands of workload.
Future
Redefine TM
A New Class Of Compute
01
Operand Ready Firing
02
Dynamic Assignment
03
Immediate Release
A task is ready to execute the moment its operands land in hardware. No clock tick. No host permission. No queue.
Static chips wait for the next pre-assigned slot and they may operate on stale data already there.
Any free compute element takes any ready task, the moment it is free. No pre-mapping, no fixed routes.
Static chips bind each task to a fixed processing element at compile time creating an artificial deadlock, where work halts for lack of access to resources, not lack of resources.
The moment a task completes, its compute element returns to the pool. Ready for whatever fires next.
Static chips leave silicon idle awaiting control between tasks.
A complete intelligence platform
Developer-First Stack
REDEFINE ships with a complete software stack, co-developed and validated alongside the hardware. Developers can deploy existing models without rewriting. For custom workloads, an extended C dialect gives expert developers direct dataflow graph control. The same code runs on simulation, FPGA prototypes, and production silicon, compressing the cycle from algorithm to deployment.
Multiple Products.
One Platform.
REDEFINETM SOFT IP
Drop-in accelerator IP for the most computationally intensive workloads.
Licensable
MuDRA
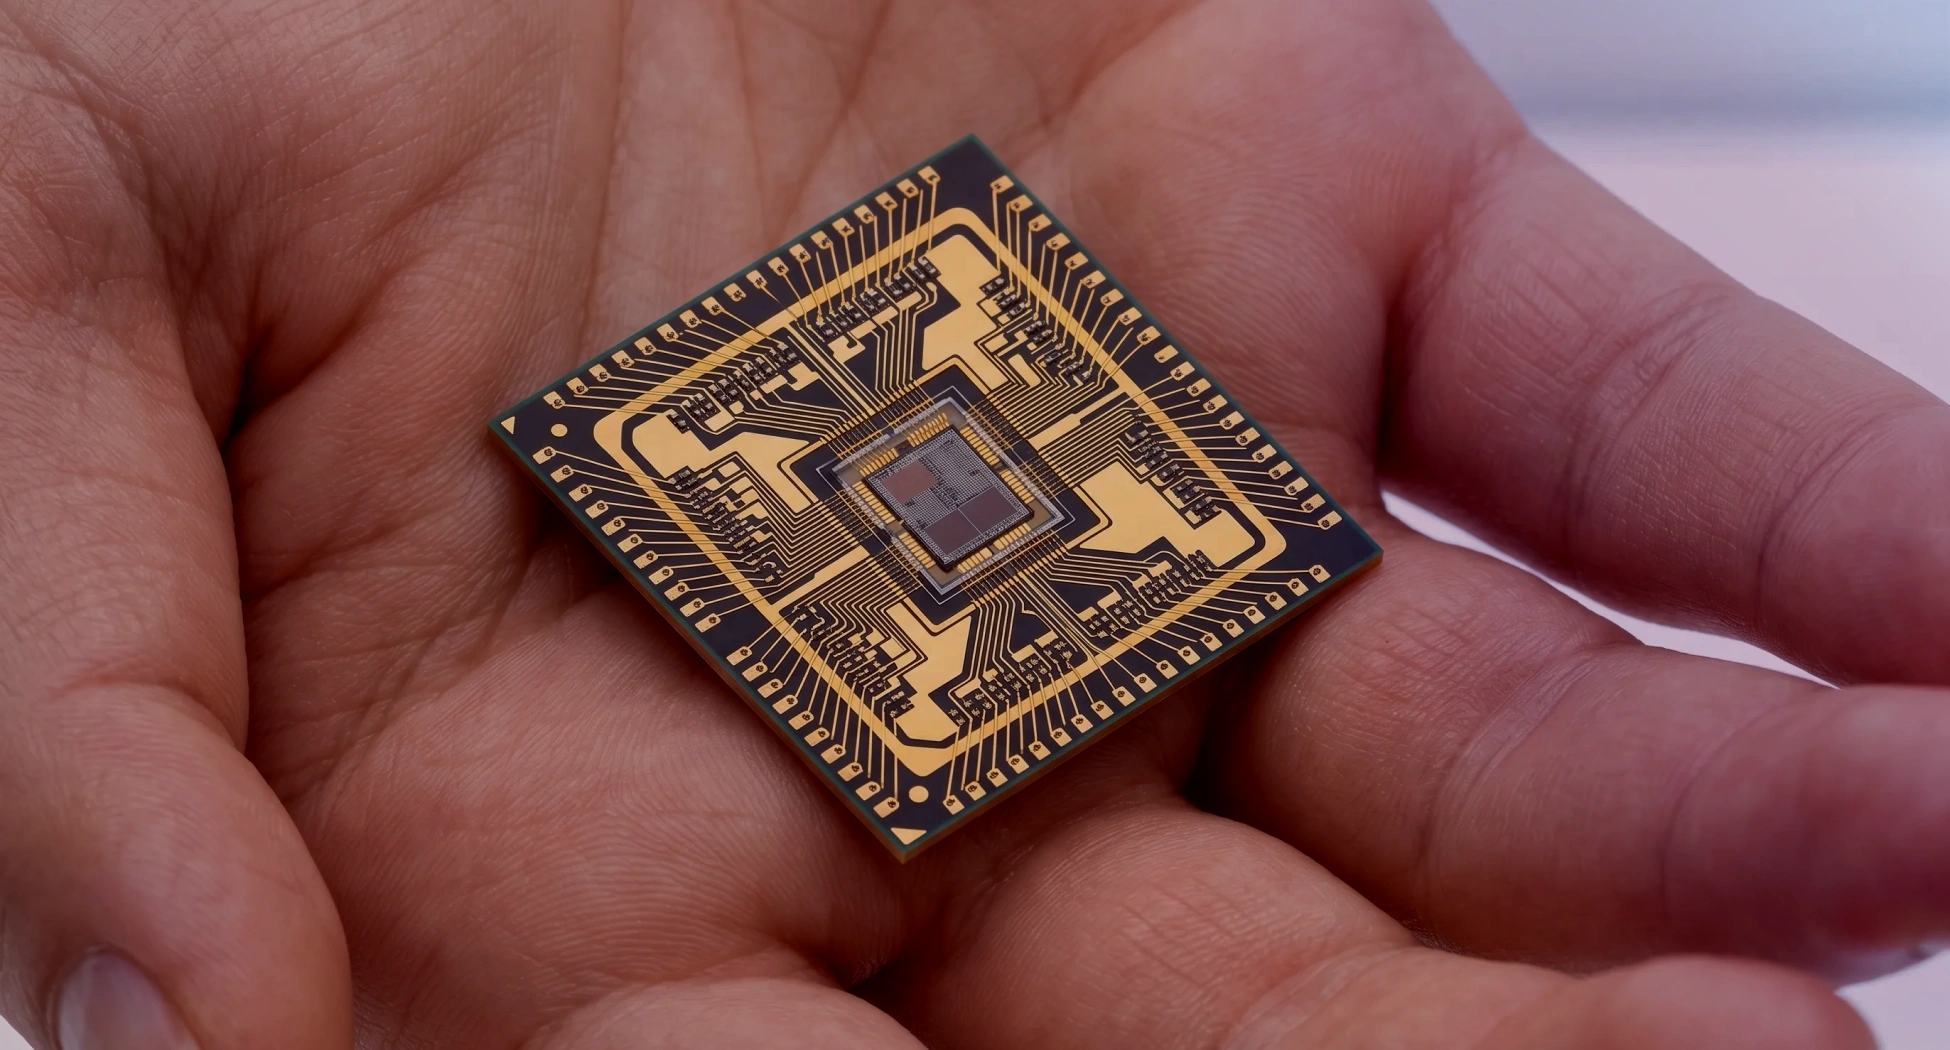
The MuDRA test chip is the physical realisation of the REDEFINE™ IP — a many-core SoC fabricated on 28nm TSMC. It is the first silicon validation of Morphing Machines' IP.
Test chip in Q3 2026. Commercial grade MuDRA follows in Q4 2027
256 KB L1 + 4 MB L2
On-chip memory hierarchy
Toroidal mesh interconnect
with distributed orchestration
51.2 GOPS INT8 performance
@ 800 MHz IP Clock
16 RISC-V cores in a 2×2 CR fabric
Each CR with 4 Compute Engines
REDEFINETM SOFT IP
Drop-in accelerator IP for the most computationally intensive workloads.
Licensable
Cloud Based Emulator
Hardware-accurate, scalable emulation for the REDEFINE™ processor on AWS cloud infrastructure — enabling software development, functional verification, and regression testing before silicon arrives.
Request Access
Your submission has been received!
COMPUTING FROM CORE TO EDGE
Core Data Centers
Run AI/ML training and inference, graph analytics, encrypted computing across BFSI and healthcare, and cybersecurity workloads, all on one fabric.
Edge Intelligence
Vision analytics, AI/ML inference, and cybersecurity systems deployed at the network edge where latency and power are critical constraints.
Embedded Systems
ADAS and autonomous systems where deterministic, low-latency intelligent compute is essential for safety-critical decisions.
Developer-Friendly Programming Model
Program REDEFINE™ in the languages and frameworks you already know, no deep hardware expertise required.
Request SDK Access
Your submission has been received!
What Will You Build?
What Will You
Every domain shapes the fabric differently. Tell us what you are running and we will walk through how it is customised at design time.
Build?
Join
The Mission
Morphing Machines is redefining how machines compute, evolve, and scale for the next era of intelligent systems.
Morphing Machines is redefining how machines compute, evolve, and scale for the next era of intelligent systems.